Point a voice agent at your own self-hosted or third-party OpenAI-compatible model, with your endpoint and your key.
Bring your own model by pointing Bolna at any endpoint that speaks the OpenAI chat completions API. Your endpoint can run anywhere: vLLM, Ollama, SGLang, TGI, a LiteLLM proxy, or a hosted gateway. Bolna calls it exactly as it calls OpenAI, only at your URL and with your key. Use this when you need a fine-tuned or open-weight model, when the weights have to stay on your own infrastructure, or when you already pay a provider directly and want the tokens billed there.
Bolna sends requests with the OpenAI SDK, so the endpoint has to behave like OpenAI’s chat completions API.
Requirement
Detail
POST {base_url}/chat/completions
Give Bolna the base URL including the version segment, for example https://your-host/v1. Bolna appends the rest of the path.
Streaming responses
OpenAI delta format, terminated by data: [DONE]. Tokens stream straight into speech synthesis, so an endpoint that only replies once the full answer is ready adds audible silence before the agent speaks.
Bearer authentication
Your key is sent in the Authorization header.
A publicly resolvable host
Private, loopback and link-local addresses are refused, both at registration and on every call.
Streamed tool_calls
Only if your agent uses tools. Support varies between self-hosted servers, so test it before relying on it.
Your model id is passed through unchanged, so it must match whatever your server expects.
Registration is refused when Bolna can prove the configuration is wrong:
The endpoint URL must resolve to a public address. Private, loopback and link-local addresses are rejected.
If the endpoint rejects the API key, you get The endpoint rejected this API key.
If the endpoint publishes a model list that does not include your model name, the error names what it does serve.
A model name must be unique within the scope that owns it, because an agent resolves its custom model by name. A duplicate is refused before the endpoint is contacted.
If the endpoint cannot be reached at all, for example because a serverless deployment has scaled to zero, the model is still saved. Verification is best effort and cannot guarantee that a model will be reachable later.
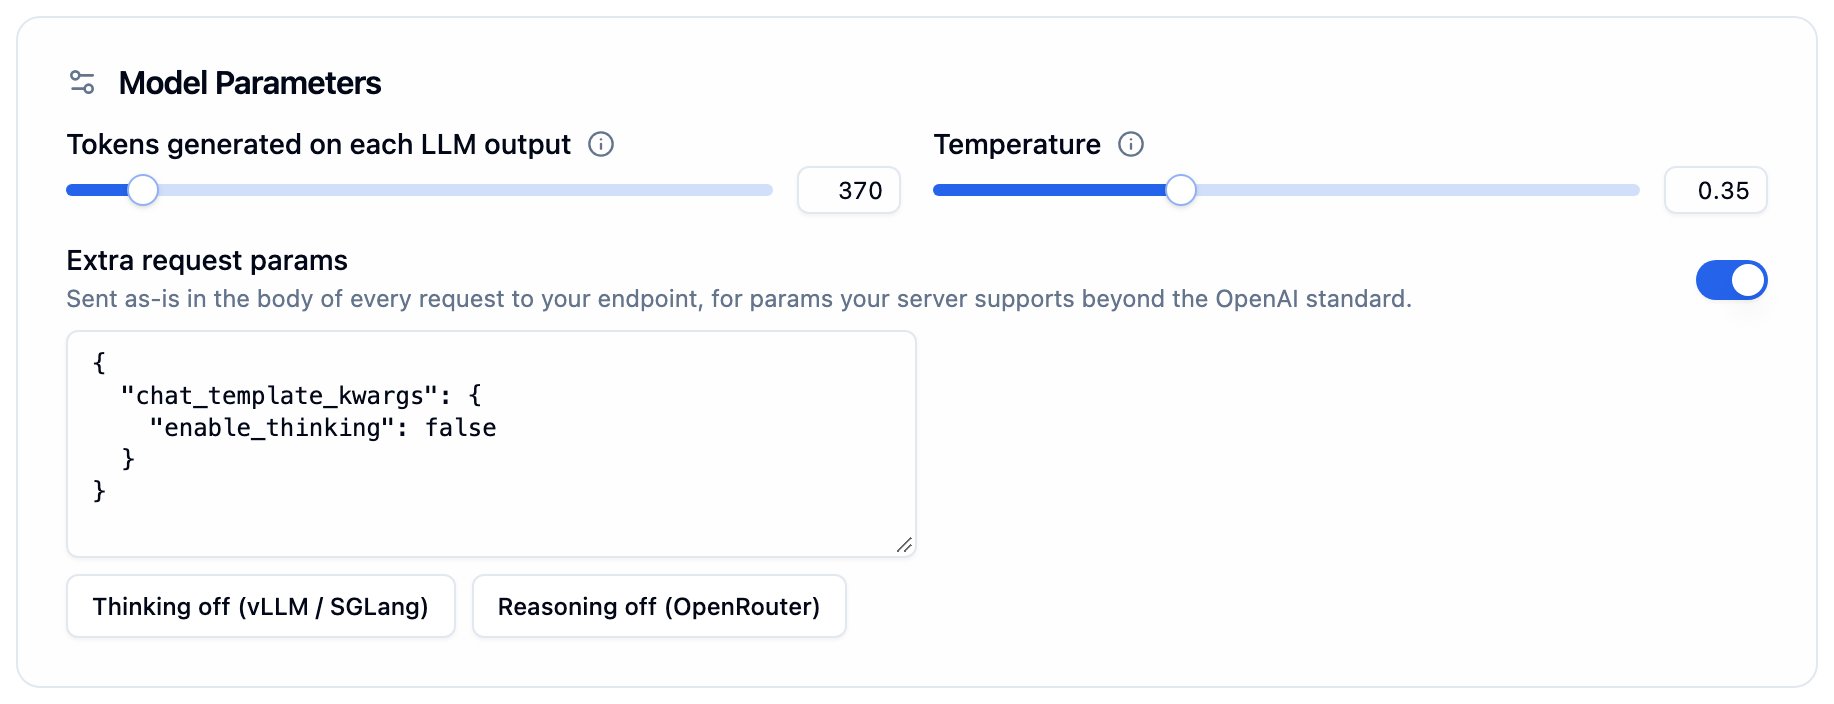
Open the agent, go to the Intelligence tab, choose custom as the provider, then pick your model. Save the agent.If your server needs parameters beyond the OpenAI standard, such as turning a model’s thinking off, switch on Extra request params on the same tab and enter them as JSON. They are sent on every request to your endpoint. See Extra request params for examples and the rules.
Many servers accept parameters that are not part of the OpenAI API, such as turning a model’s thinking off. Set them in extra_body and Bolna adds them to every request it sends to your endpoint.
Each key is sent as a top-level field of the request body, exactly as the OpenAI SDK’s extra_body does, so the request above reaches your server as {"model": "Qwen/Qwen3-8B", "messages": [...], "chat_template_kwargs": {"enable_thinking": false}, ...}.Common examples:
It is set per agent, so two agents on the same model can differ. The params go on every request to your endpoint: conversation turns, graph agent routing, and the end-of-call and voicemail checks. Turning thinking off therefore speeds up routing as well as replies.In the dashboard, open the agent’s Intelligence tab with your custom model selected and switch on Extra request params. Type the JSON, or start from one of the example buttons.
Extra request params under Model Parameters, shown when a custom model is selected
Saving the agent is refused when:
extra_body is not a JSON object
the agent’s provider is not custom, since hosted providers never receive extra params
it sets a field Bolna controls: model, messages, stream, stream_options, tools, tool_choice, parallel_tool_calls or response_format
Bolna cannot know which params your server accepts. A misspelled or unsupported key is saved, and your server then either ignores it or rejects every request with a 400, which leaves the agent silent. Test a new extra_body with a web call before putting the agent on live traffic.
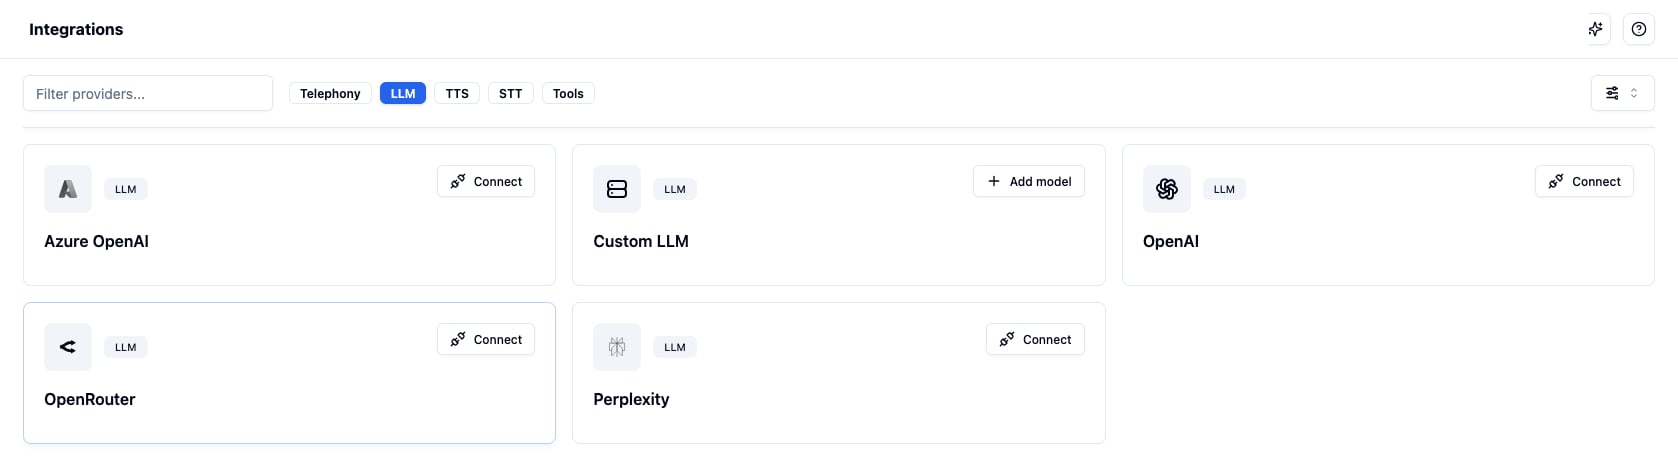
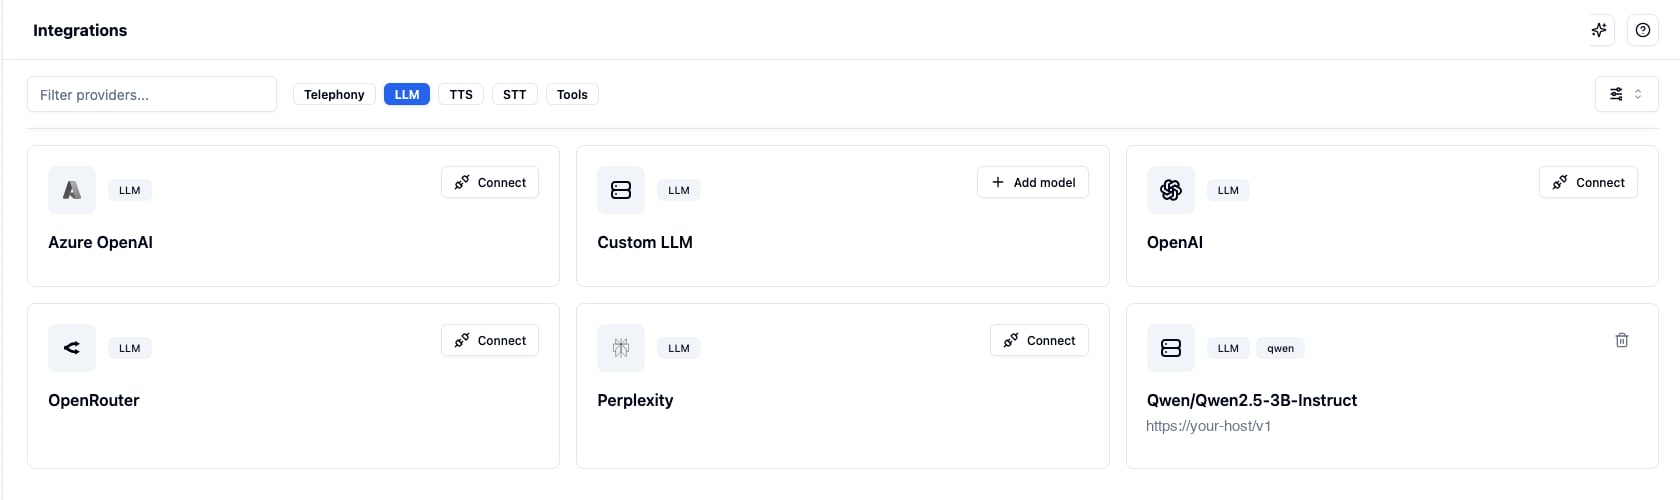
Delete a model from its card on the Integrations page. A model that is still selected on an agent cannot be deleted: the error names the agents using it, so you can point them at another model first. This applies to every agent config, including graph agent nodes.Deleting a model also removes the stored API key.
A custom model belongs to the scope it was created in:
A model added on your main account is available to the account and to all of its sub-accounts.
A model added inside a sub-account is available only in that sub-account. It is not visible to the main account or to other sub-accounts, and neither can delete it.
Does Bolna use the OpenAI Responses API for custom models?
No. Custom models always use chat completions, because the Responses API’s server-side conversation chaining is specific to OpenAI and a self-hosted server cannot resolve a previous response id.
How do I turn thinking off on my reasoning model?
Set it in extra_body with the parameter your server uses. On vLLM or SGLang with Qwen3 that is {"chat_template_kwargs": {"enable_thinking": false}}. Thinking adds silence before every reply, so voice agents usually want it off.
Does Bolna send service_tier to my endpoint?
No. service_tier is an OpenAI-only field that strict OpenAI-compatible servers reject, so it is never sent to a custom endpoint.
What happens if my endpoint has scaled to zero?
The first call pays the cold start, which the caller hears as silence before the agent speaks. Keep a warm instance if first-token latency matters. Registration tolerates an unreachable endpoint, so scaling to zero does not block you from adding the model.
Who bills me for the tokens?
Your provider. Bolna records a custom model’s token usage against your own endpoint, so that model’s inference is not billed by Bolna.
Can a sub-account have its own custom model?
Yes. A model added on the account is available to it and to all of its sub-accounts. A model added inside a sub-account stays in that sub-account, invisible to the main account and to sibling sub-accounts.
Can I point an agent at a model on a private network?
No. The endpoint must resolve to a public address. Expose it through a public hostname, with your key as the bearer token.